What people mean by “booter”
In underground slang, a booter is a paid service that launches denial-of-service traffic on demand. The word overlaps with “stresser,” which is why educational pages must separate abuse from engineering practice.
Search engines still surface both terms. When you evaluate a vendor, ignore the buzzword and inspect whether targets are verified, accounts are identifiable, and policies ban third-party attacks. Start with Definition & Uses if you need the neutral vocabulary.
This section expands on What people mean by “booter” for teams that need more than a one-line definition. Authorized stress testing is a measurement discipline: you apply controlled load to infrastructure you own, watch where it bends, and feed the findings into capacity and protection work.
Write down the hypothesis before you start. If you cannot explain what failure mode you expect to observe, you are not ready to choose a method or concurrency. Short iterative runs with clear abort criteria beat a single unmanaged peak.
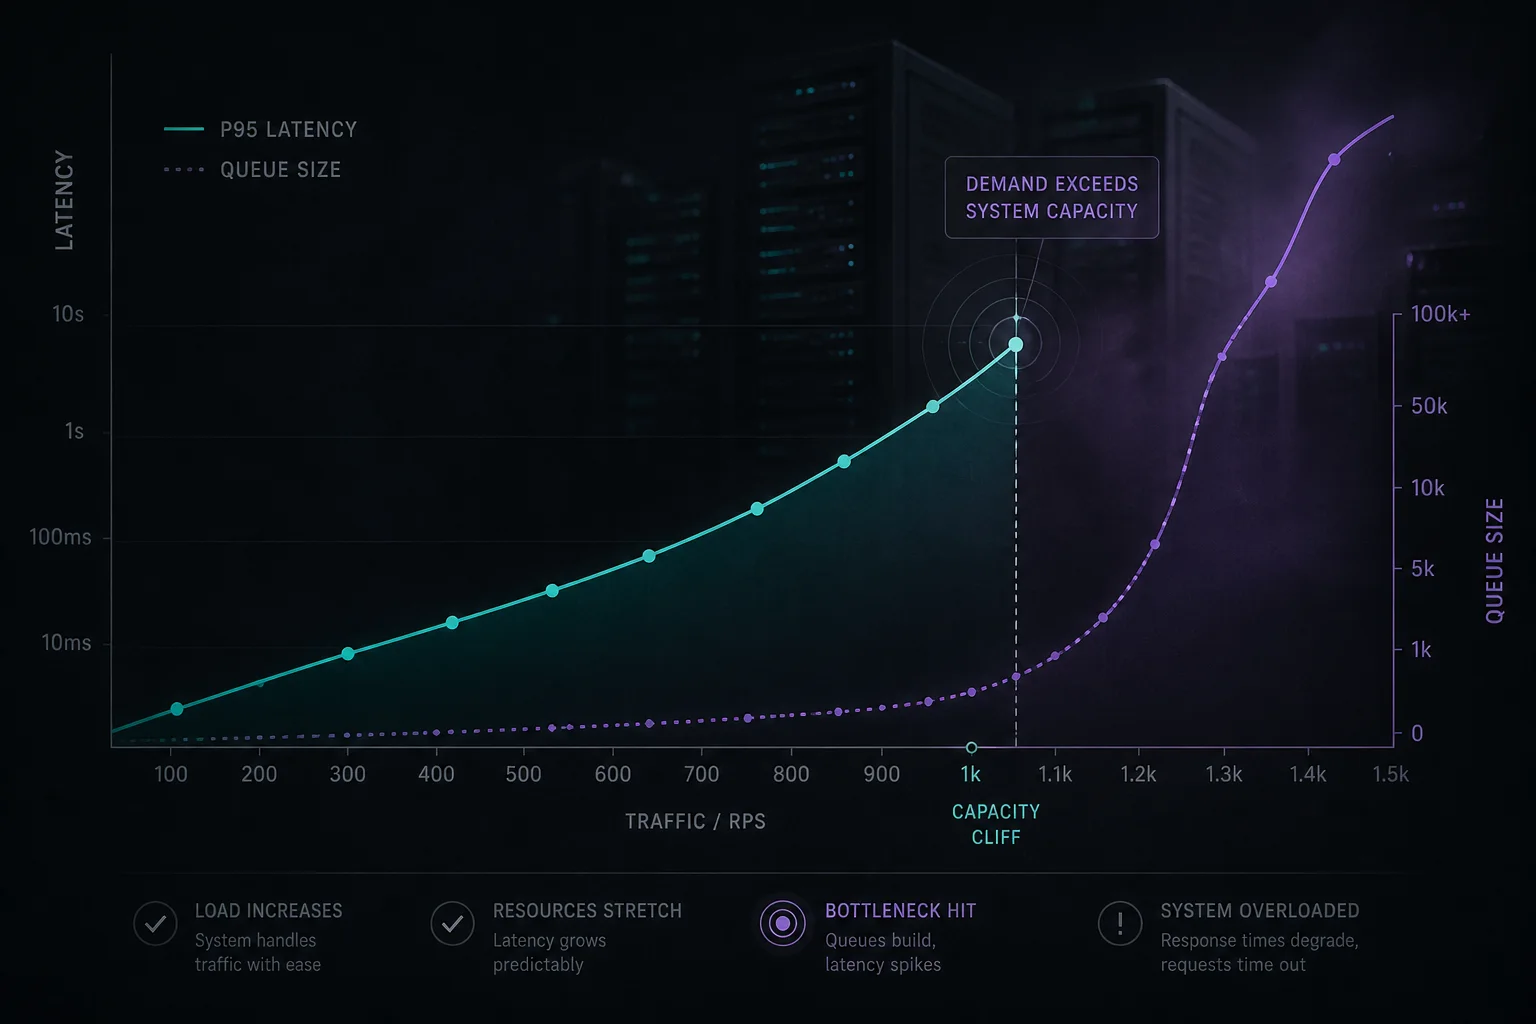
Pair every run with observability on both the edge and the origin. Latency percentiles, error rates, connection-table pressure, WAF challenges, and recovery after stop are the signals that turn traffic into decisions.
Keep the work accountable. Use identifiable accounts, verified targets, and published rules such as Slammed.st Acceptable Use. Browse related material on the blog when you need adjacent topics.
Legal and operational risks
Using a booter against systems without authorization can bring criminal charges, civil claims, and provider bans. Operators of illegal booters have been dismantled in multiple countries; customer databases have been seized.
Even “just testing a friend’s game server” without permission can cross the line. If you need capacity data, get written authorization and use a platform that logs accountable activity.
This section expands on Legal and operational risks for teams that need more than a one-line definition. Authorized stress testing is a measurement discipline: you apply controlled load to infrastructure you own, watch where it bends, and feed the findings into capacity and protection work.
Write down the hypothesis before you start. If you cannot explain what failure mode you expect to observe, you are not ready to choose a method or concurrency. Short iterative runs with clear abort criteria beat a single unmanaged peak.
Pair every run with observability on both the edge and the origin. Latency percentiles, error rates, connection-table pressure, WAF challenges, and recovery after stop are the signals that turn traffic into decisions.
Keep the work accountable. Use identifiable accounts, verified targets, and published rules such as Slammed.st Acceptable Use. Browse related material on the blog when you need adjacent topics.
Operations notes and common pitfalls
Teams often under-communicate. A stress window that is “known to engineering” but unknown to the NOC still creates chaos. Publish a short advisory: start/stop time, expected symptoms, escalation contact, and the exact targets in scope.
Another frequent mistake is changing too many variables at once — method, concurrency, cache rules, and WAF mode in a single run. Change one primary variable per iteration so causality stays clear when you write the post-test report.
Finally, budget time for recovery validation. Confirm that queues drain, autoscaling cools down, and error rates return to baseline after stop. If recovery is sticky, that finding is as important as the peak breaking point. See the authorized checklist and best practices for fuller process detail.
When you are ready to execute on verified infrastructure, create a Slammed.st account and size the plan to the hypothesis — not to a marketing Gbps number. Pricing context lives on the pricing page.