What Are IP Stressers?
An IP stresser (also called an IP booter) is a tool that generates network or application traffic toward a target IP address or URL. The goal is to measure how the system behaves under load — latency, packet loss, error rates, connection limits, and capacity ceilings.
In a legitimate setting, stressers are used as a controlled testing tool against infrastructure you own or are explicitly authorized to test. Unauthorized attacks against third-party services are illegal and violate the policies of responsible platforms.
Teams use stress testing to find bottlenecks before customers do: firewalls that drop under SYN pressure, APIs that time out at peak, CDNs that need cache tuning, origin servers that cannot keep concurrent connections, or rate-limit rules that fire too early on real traffic patterns.
Modern platforms package methods into presets so operators do not hand-craft every packet. You choose a method, duration, concurrency, and target; remote workers emit traffic while the control plane tracks status and enforces stop conditions.
Historically, organizations discovered capacity limits only during outages. An IP stresser flips that sequence: you schedule a controlled probe and learn which component fails first while stakeholders are watching on purpose.
Useful targets include origin fleets, reverse proxies, API gateways, game or voice endpoints you operate, and lab replicas that mirror production limits. Useless or unlawful targets include anything you do not own and have not been contracted to assess.
When stakeholders ask “is a stresser the same as a booter?”, answer with process, not slang. If there is identity, authorization, monitoring, and a stop plan, you are in engineering territory. If there is anonymity and third-party disruption, you are not. See Booters explained.
Product teams also use stress windows to validate autoscaling policies and cache hit ratios under concurrency that marketing forecasts imply but staging rarely reproduces. Capturing those numbers early is cheaper than an incident postmortem.
How Do Stressers Work?
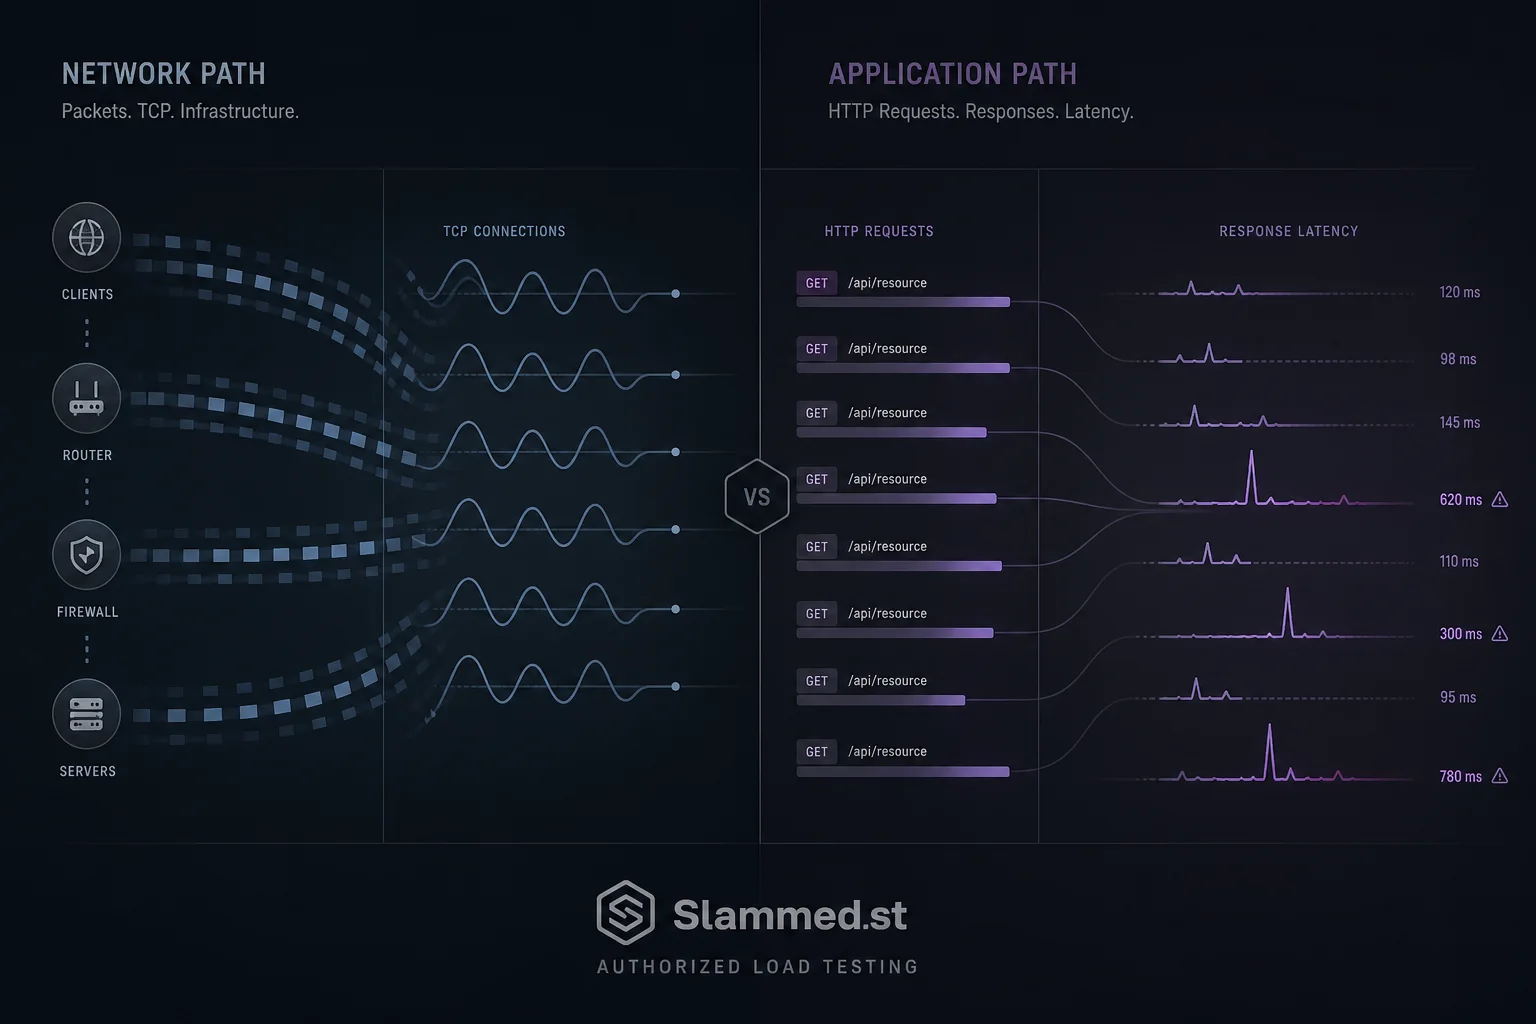
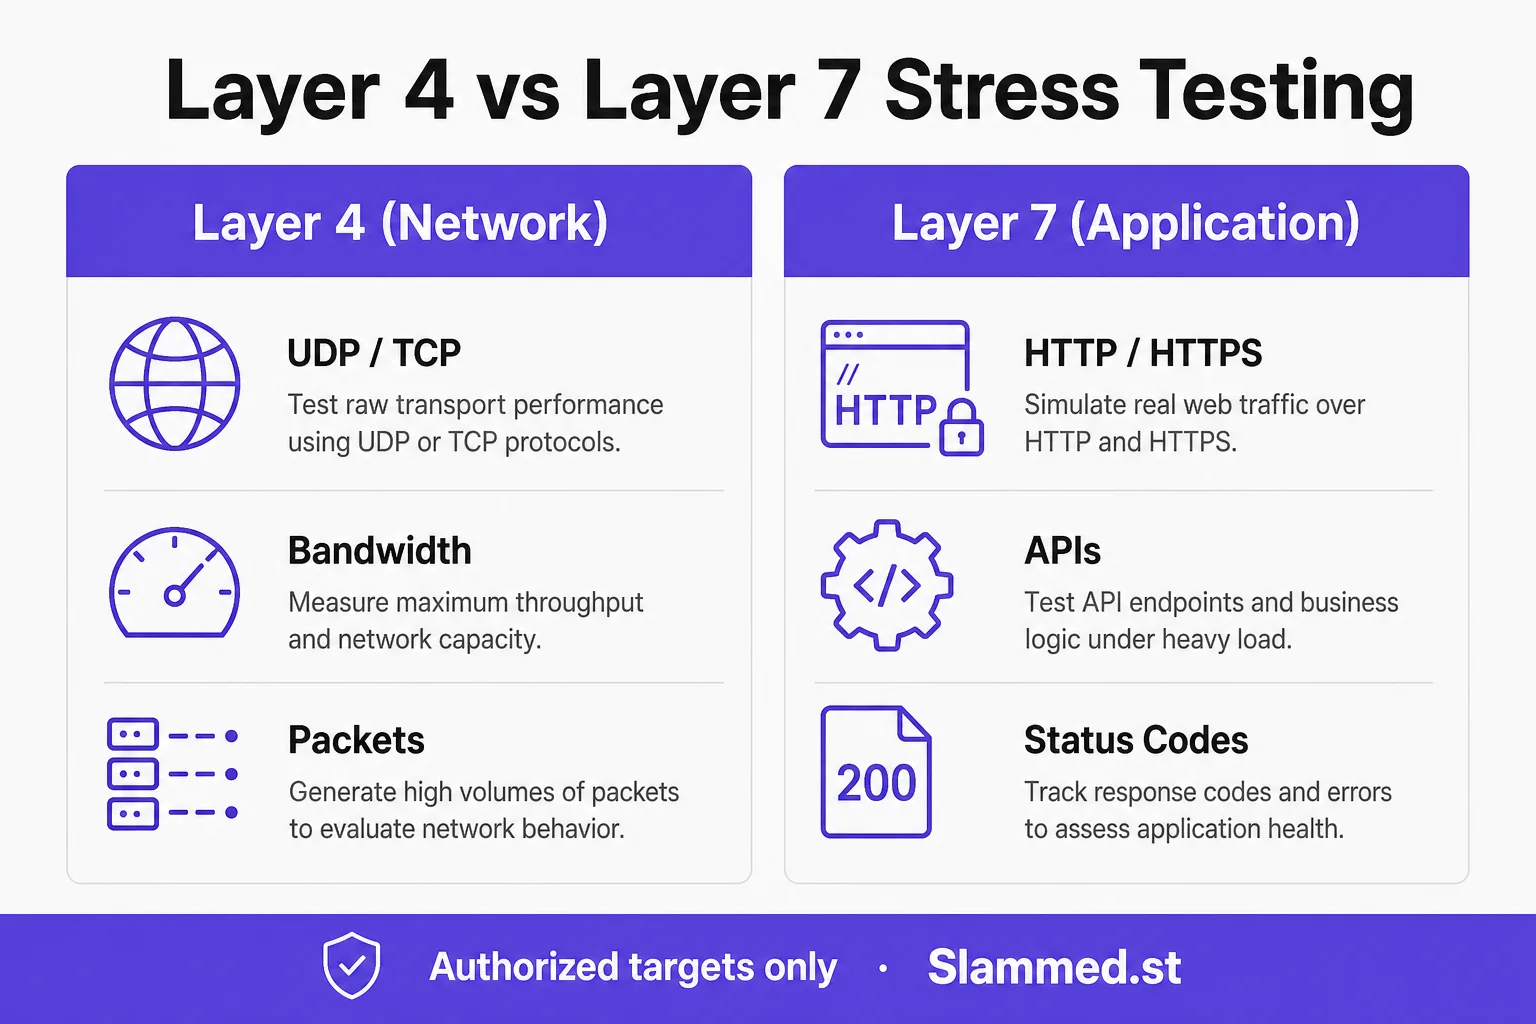
Most stressers offer Layer 4 (transport) and Layer 7 (application) methods. L4 scenarios exercise TCP/UDP paths and bandwidth; L7 scenarios mimic HTTP(S) clients hitting pages, forms, and APIs with realistic headers and keep-alive behavior.
A typical authorized workflow looks like this:
- Verify ownership or written permission for the target, including the testing window.
- Choose method, duration, and concurrency that match the failure mode you want to observe.
- Run traffic from remote nodes while monitoring latency, errors, CPU, NIC, and firewall counters.
- Stop the test on schedule, review results, and harden or scale as needed.
Quality platforms also enforce plan limits, abuse detection, and target verification so capacity tests stay controlled. That operational discipline is what separates engineering tools from anonymous attack shops. For a deeper walkthrough of L4 vs L7, see Layer 4 vs Layer 7 stress testing.
Under the hood, workers open connections or craft packets according to the selected method while the control plane enforces duration and concurrency caps from your plan. You should always know how to stop a run from the UI or API within seconds.
Layer selection is a first-class decision. L4 answers questions about bandwidth, SYN/connection tables, and scrubbing. L7 answers questions about HTTP paths, TLS termination, and application queues. Mixing them without a hypothesis muddies the result — details in L4 vs L7.
Good runs are boringly well-instrumented. Assign a driver for the stresser UI, a watcher for edge dashboards, and a watcher for origin APM. Agree in advance which metric trips an abort so nobody debates mid-test.
After stop, leave five to fifteen minutes for cool-down observation. Sticky queues, slow scale-in, or elevated error rates after traffic ends are findings you will miss if you close the laptop immediately.
How Are Stressers Misused?
The same traffic techniques can be abused for disruption. Criminal “booter” services market illegal DDoS-for-hire with anonymous payment and no target checks. That activity is unlawful in most jurisdictions and can lead to civil and criminal liability for both operators and customers.
Responsible operators separate authorized load testing from attack-for-hire. Slammed.st requires verified targets and prohibits testing systems you do not control. Read Booters explained for the slang, legal risk, and the authorized alternative.
Abuse markets advertise “boot minutes” and anonymous payment. Lawful platforms advertise plans, invoices, support, and target checks. That packaging difference is not cosmetic — it is the compliance boundary your security team cares about.
Even well-intentioned engineers can drift into risk by testing a partner’s host “just to see” without a written window. Treat permission as a deliverable, same as a monitoring checklist.
If your organization was previously hit by a booter, authorized re-tests of your mitigations are appropriate; retaliatory traffic is not. Channel energy into protection validation instead.
Can You Prevent Booter Attacks?
You cannot eliminate every risk, but you can reduce impact:
- Use DDoS-aware DNS/CDN and scrubbing where appropriate.
- Rate-limit and challenge abusive L7 traffic at the edge.
- Capacity-plan with scheduled, authorized stress tests against your own stack.
- Keep runbooks for blackhole, failover, and provider escalation.
- Monitor baseline traffic so anomalies are obvious during an incident.
Regular authorized tests help you learn where protection fails — before an attacker does. Pair this guide with How to run an authorized stress test for a practical checklist.
Prevention is layered: reduce attack surface, absorb or scrub volumetric noise, challenge abusive L7 patterns, and rehearse escalation. No single appliance makes you “DDoS-proof.”
Authorized stress tests are how you prove each layer still works after config drift — a new WAF rule, a CDN provider change, or a firewall firmware bump can quietly undo last quarter’s hardening.
Store baselines from quiet periods so you can compare during a controlled run. Without baselines, every spike looks surprising and every mitigation looks successful.
For the operational sequence from permission to postmortem notes, use How to run an authorized stress test.
Operations notes and common pitfalls
Teams often under-communicate. A stress window that is “known to engineering” but unknown to the NOC still creates chaos. Publish a short advisory: start/stop time, expected symptoms, escalation contact, and the exact targets in scope.
Another frequent mistake is changing too many variables at once — method, concurrency, cache rules, and WAF mode in a single run. Change one primary variable per iteration so causality stays clear when you write the post-test report.
Finally, budget time for recovery validation. Confirm that queues drain, autoscaling cools down, and error rates return to baseline after stop. If recovery is sticky, that finding is as important as the peak breaking point. See the authorized checklist and best practices for fuller process detail.
When you are ready to execute on verified infrastructure, create a Slammed.st account and size the plan to the hypothesis — not to a marketing Gbps number. Pricing context lives on the pricing page.