Preparing for 50k-100k RPS starts with the right question
Teams often say they want to prepare a server or API for 50k-100k RPS, but the number alone is not the plan. You need to know what kind of requests those are, how cacheable they are, whether they hit the same dependencies, and what latency or error budget defines success. Fifty thousand cache-hit homepage requests are a different engineering problem from fifty thousand authenticated checkout calls.
That is why the first step is to define the traffic shape before you define the tooling. Are you testing edge capacity, origin behavior, a narrow API route, or a complete user flow? The answer determines whether you focus on Layer 7 application realism, Layer 4 transport behavior, or a staged sequence of both. It also determines what "ready" should mean on the day of the test.
For the method split, review L4 vs L7 when to use each. For event-style traffic preparation, pair this article with stress testing before Black Friday.
Find the first bottleneck before chasing the headline RPS number
Most systems do not fail everywhere at once. They fail at the first narrow point: connection pooling, database saturation, queue backlog, origin shield weakness, CPU exhaustion at TLS termination, or an autoscaling policy that reacts too slowly. If you jump straight to the biggest RPS target without isolating those bottlenecks, you can create a lot of heat without learning much.
A better approach is incremental. Establish a baseline, ramp steadily, and watch which layer deviates first. If latency rises while CPU stays low, the problem may be downstream. If edge looks stable but origin misses explode, caching or request routing may be the issue. If packet or connection behavior fails early, the network layer may need attention before the application layer can be evaluated fairly.
This step is where a disciplined authorized load-testing workflow pays off. You want runs that are small enough to diagnose, large enough to reveal the limit, and easy to repeat after remediation.
Separate edge readiness from origin and dependency readiness
At 50k-100k RPS, edge and origin are often telling different stories. A CDN can look healthy while the origin path degrades badly on misses. A homepage can perform well while login or checkout routes break because they bypass the cache and hit expensive downstream services. Treating the whole stack like one number hides the exact place where risk lives.
Split your readiness plan into layers. For edge: watch cache hit ratio, TLS behavior, request distribution, and how the WAF behaves under legitimate concurrency. For origin: watch p95 and p99 latency, thread or worker saturation, database pool health, queue depth, and dependency timeouts. For critical APIs: watch route-level performance and error codes, not just aggregate throughput.
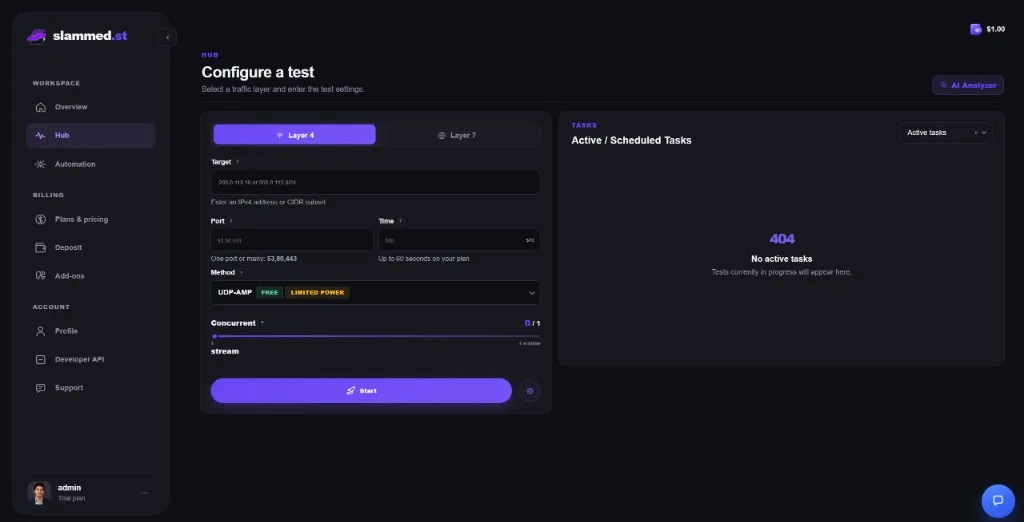
If your organization needs a guided panel for these exercises, inspect /features and /#how to understand how authorized traffic windows are structured.
Attach observability before you attempt 50k-100k RPS
High-RPS tests are worthless if you cannot explain the result. Before the run, decide exactly which dashboards and alerts matter. That usually includes application latency, error rate, request breakdown by route, cache hit ratio, origin response, database health, queue depth, autoscaling signals, and infrastructure counters at the edge. If you use a third-party CDN or WAF, ensure the relevant stakeholders know the window is intentional.
You should also define success and abort thresholds ahead of time. For example, it may be acceptable for p99 to rise briefly during a ramp, but not for checkout errors to exceed a certain percentage. Writing those thresholds down keeps the team from arguing about them while the test is live. It also makes retests more comparable because the same decision framework is applied each time.
The legal and operational side of that preparation is summarized at /authorized-load-testing and the 2026 checklist.
Build toward 50k-100k RPS in measured steps
The safest route to 50k-100k RPS is a layered one: define the exact route mix, isolate the first bottleneck, separate edge from origin, attach observability, run an authorized rehearsal, fix the constraint, and repeat. That process is slower than chasing a screenshot, but it is how teams actually become ready.
Continue with tool selection, developer workflow guidance, and retail-event preparation. If you need a managed next step, review pricing and authorized load testing.