Why every authorized load test needs a checklist in 2026
Authorized load testing has matured. In 2026, the biggest mistakes are rarely about whether a team can generate traffic. They are about whether the team can prove the traffic was approved, scoped correctly, monitored properly, and stopped quickly if the environment behaves unexpectedly. A checklist is the simplest way to make that discipline repeatable.
Without one, organizations rely on memory and assumptions. Someone forgets to notify the CDN, someone assumes staging and production have the same limits, or someone launches a route that was not actually covered by the original approval. Those are avoidable failures, and they are exactly why the authorized framing at /authorized-load-testing should come before any launch window.
This article acts as a hub for safe preparation. It is designed for engineering teams, SREs, security, and operators who need a repeatable path from approval to evidence.
Checklist step 1: verify scope target ownership and timing
Start by confirming the target. Do you own the hostname, IP, environment, and provider account involved in the exercise, or do you have written permission from the owner? Then define the exact scope: which endpoints, which methods, what intensity, what time window, and what surrounding infrastructure may be affected. If that information is vague, the test is not ready.
Do not treat broad statements like "our app" as enough. In high-stakes tests, the important difference may be between CDN edge, API origin, a worker cluster, or a single expensive route. Writing the scope clearly forces alignment and prevents accidental spillover into systems the team did not intend to exercise.
This is also the best time to align on whether the run is L4, L7, or a sequence of both. The method guide at L4 vs L7 when to use each helps teams make that decision explicitly.
Checklist step 2: align stakeholders and monitoring
Once scope is defined, identify who needs to know. That normally includes SRE, application owners, security, hosting or cloud contacts, CDN or WAF operators, and anyone on incident duty who might otherwise treat the run as a live attack. A planned test should never look like a surprise to the people responsible for uptime.
At the same time, define the monitoring package. Decide which dashboards will be open, who will watch them, and what thresholds matter. Route-level latency, cache hit ratio, queue depth, database pool health, CPU, memory, network counters, and edge behavior all matter in different combinations depending on the target. If you do not know what you plan to observe, you are not ready to generate meaningful traffic.
Teams that want an operations-ready workflow can cross-reference /#how and /features with their own runbooks before the first large test.
Checklist step 3: choose a provider with verification and controls
The provider should strengthen your process, not weaken it. That means visible legal pages, account-based access, target verification, clear plans, and support that exists during the window that matters. If a service markets itself around anonymity or absent rules, it is pushing you away from authorized discipline and toward avoidable risk.
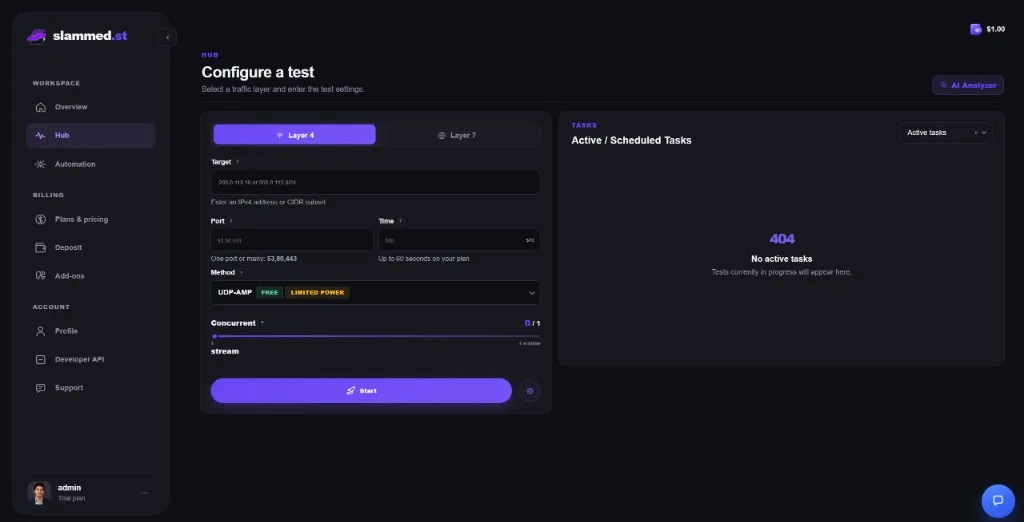
A provider should also match the workload. If the hypothesis is about application behavior, you need practical Layer 7 options. If the hypothesis is about perimeter or network transport, Layer 4 may matter more. In both cases, you need stop controls and a clear idea of who can intervene if the test behaves unexpectedly.
Buyer-focused guidance lives in Best IP Stresser 2026, while legal context sits in is using an IP stresser legal.
Checklist step 4: define success abort criteria and rollback actions
Before launch, write down what success looks like and what would trigger a stop. Success might mean sustaining a target concurrency or RPS range while staying inside a latency and error budget. Abort criteria might include a specific p99 threshold, database exhaustion, origin instability, or signs that a shared provider is reacting in an unsafe way. The important point is that nobody should invent these rules in the middle of the run.
Rollback and response actions matter too. If the test exposes a weakness, who owns the remediation? If the route degrades, can traffic be cut immediately? If a provider or partner asks questions, who answers them? A mature test window treats these questions as part of preparation, not as optional extras.
This is one reason that public policy pages such as /legal and /terms are useful. They help the team align its own rules with the service rules before anything is launched.
Checklist step 5: launch document remediate and retest
At launch time, keep the workflow calm and explicit. Verify the exact target again, confirm observers are present, and run the planned scenario rather than improvising new intensity in the moment. During the test, capture key timestamps, notable deviations, and any operator decisions that affect the interpretation of results.
After the run, document what happened, what failed first, and what changes should be made before the next rehearsal. Then retest with the same checklist. That repeat loop is what makes authorized load testing a capacity discipline instead of a one-time stunt. It is also how organizations build confidence ahead of launches, migrations, and campaign events.
For a managed next step, review /pricing, create access at /register, and keep the hub at /authorized-load-testing as the central reference for future runs.
Related guides for your next authorized load test
Continue with preparing for 50k-100k RPS, Black Friday stress testing, developer workflows, and booter vs authorized comparisons. The more your process is documented before the run, the safer and more useful the results become.